MCRIT Web
This document outlines the different functionalities of the MCRIT web frontend.
First Usage
After installation (e.g. via docker) and when starting MCRIT Web for the first time, you will be greeted with the following screen:

You will need to register your primary user first, which will automatically be assigned the admin role and have maximimum access rights.
It can also never be degraded from admin.
The server details allow you specify an MCRIT backend, which by default is listening on port 8000.
The mcrit-server hostname is the preset from docker-mcrit, if you are running a standalone deployment, you will also have to change the address, possibly to 127.0.0.1 or similar, depending on your setup.
If you want a multi-user instance, you can specify an optional registration token, allowing you to prohibit open registration on your server, e.g. when you want to have it facing to the open internet.
Functionality
We will now give an overview of the different functional aspects and menus of MCRIT Web.
Explore
The explore menu allows you to navigate and access the contents stored in your MCRIT instance.
Search
MCRIT provides a search interface, with which you can search various data points of stored families, samples, and functions.
The search syntax either allows to simply use plain search terms or to prefix your search terms in order to limit the search to specific fields.
For example, when only looking for samples of a certain family_name, you could use:
The currently supported fields per category are:
- families:
- samples:
- family_id
- sample_id
- sha256
- filename
- family
- version
- component
- functions:
- family_id
- sample_id
- function_id
- offset
- pichash
- function_name
- num_instructions
Additionally, you can also use operands to further limit the term:
<, <=, >, >= -> limit the range!= -> not equal! -> logical not? -> match anywhere in the field, as a literal substring rather than a pattern
Furthermore, search terms can be combined using the AND and OR directives, e.g. like so:
family_id:1 AND offset:<=0x2399fff AND offset:>=0x2398fff
A term that is exactly a family, sample or function id - or a sample's sha256 - also
matches that record directly, on top of every record whose text contains the term.
Those exact hits are flagged with an ID match or SHA256 match badge at the start of
their row, so they can be told apart from an incidental substring hit. This works the same way
on the search page and on the family, sample and function listings. An exact hit is
listed once, at the top of the first page of results; paging onwards shows the text hits
alone.
The result tables can be sorted by clicking a column header.
The sort order you last chose is remembered separately for families, samples, and functions, and stays in effect for the rest of your browser session - a new search or a return to one of the lists keeps it, while logging out clears it.
A link that already carries sort parameters always wins over the remembered order, so a shared URL shows everyone the same table.
Plain terms and prefixed terms are not the same search
A term with no field prefix is matched as a case-insensitive substring of every field
listed above for that category. A term with a prefix and no operand is matched
exactly: function_name:memcpy finds the function called memcpy, not the ones
called memcpy_s. Use ? when you want a substring of one named field
(function_name:?memcpy).
The difference is worth knowing for functions. A plain term has to be compared against
the name of every function in the database, and when nothing matches there is no partial
result to stop at, so the search reads all of them — on a large instance that takes tens
of seconds. An exact function_name: term is answered from an index instead and does not
have that cost. This is also why Functions starts unticked on the combined search page:
tick it when you want them, and prefix the term if you already know the whole name.
Families
By default, there will be always a family with family_id=0, which is reserved for all samples that have not been assigned to another family with a family_name.
The list of families gives a quick overview on how many samples there are for a given family and if the family is considered a library.
The search bar allows using the syntax described above to filter the list.

On the far right, there are four operations available to interact with the families:
- Matching: create a new matching job, and preselect this family
- Blocks: Run a Blocks analysis over the family, isolating all basic blocks unique to this family and trying to derive a YARA rule for the family
- Export: export all samples and their functions
- Edit: allows to change the family name, decide whether the family is a library or not, or delete the family
Samples
Similar to the families view, the samples view allows to inspect all samples in the MCRIT database.
The search bar allows using the syntax described above to filter the list.

The same operations as for families are available here as well:
- Matching: create a new matching job, and preselect this sample
- Blocks: Run a Blocks analysis over this sample, isolating all basic blocks unique to this sample and trying to derive a YARA rule for it
- Edit: allows to change the family name and version, decide whether the sample is a library or not, or delete the sample
Functions
Finally, the functions view provides a list of all functions.
The search bar allows using the syntax described above to filter the list.

From this view, you can create matching jobs for the function's sample.
When selecting a function shown in the table, you can open the function details.
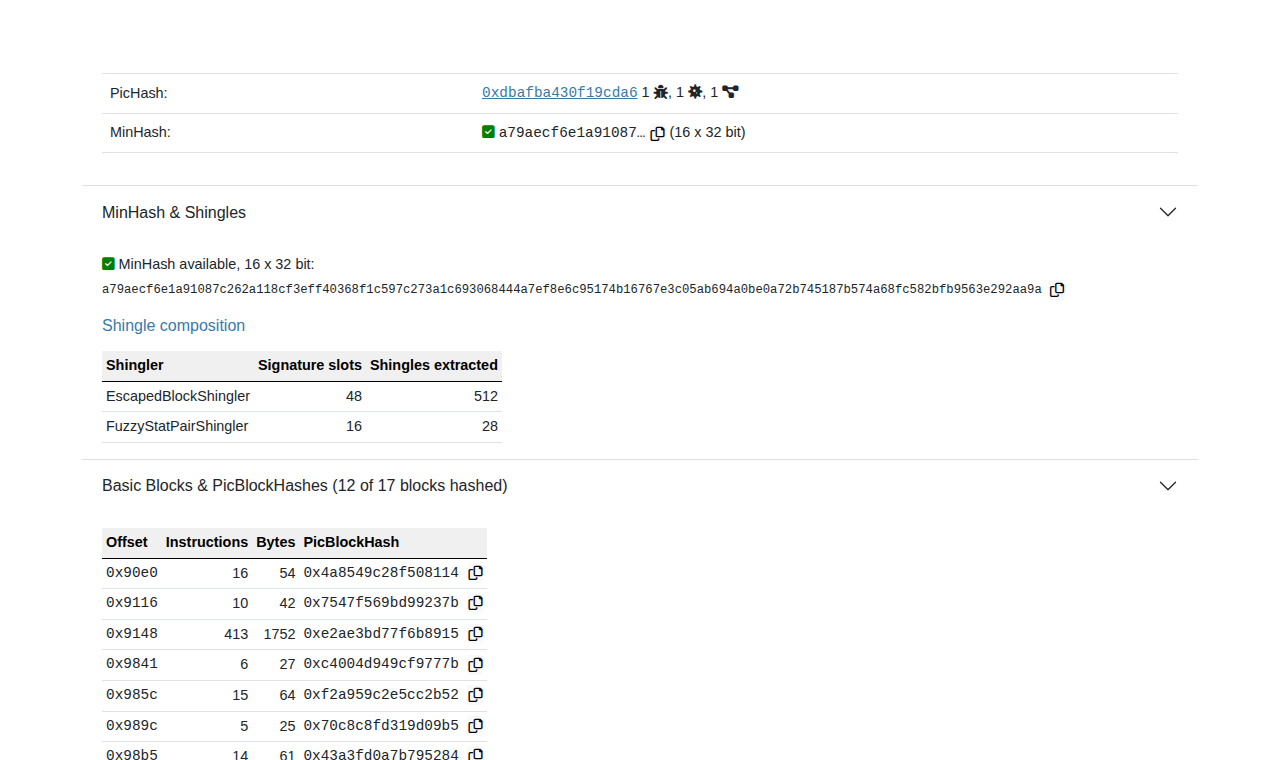
This sub view provides more information about the function, including a rendering of its control flow graph and occurrency of its basic blocks across the database:

The page is organized in collapsible sections:
- Function Info: sample and family, offset, name and labels, size, PicHash with how many families/samples/functions share it, and whether a MinHash has been calculated for the function.
- MinHash & Shingles: the MinHash signature itself and, if the backend tracks it (
MINHASH_TRACK_SHINGLES), which shingler produced how many of its slots.
- Basic Blocks & PicBlockHashes: the basic blocks the backend indexed with their PicBlockHash.
- Control Flow Graph: the CFG, with the occurrence of every basic block across the database listed next to it.
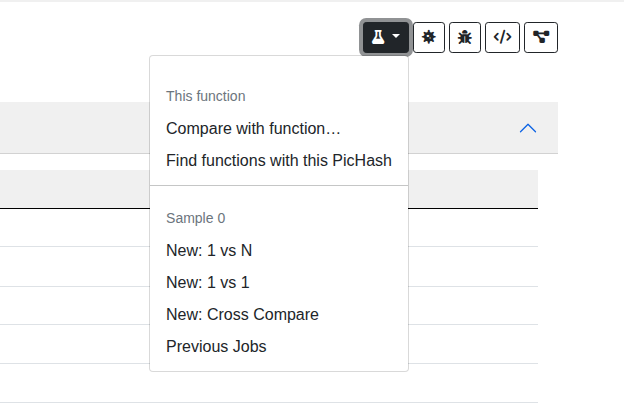
The buttons in the top right corner open the analyze menu, lead to the function's sample and family, show the API usage and jump to the CFG.
The analyze menu starts a 1vsN, 1vs1 or cross compare job for the sample, searches for all functions sharing the PicHash, or compares this function with any other stored function by its function_id:
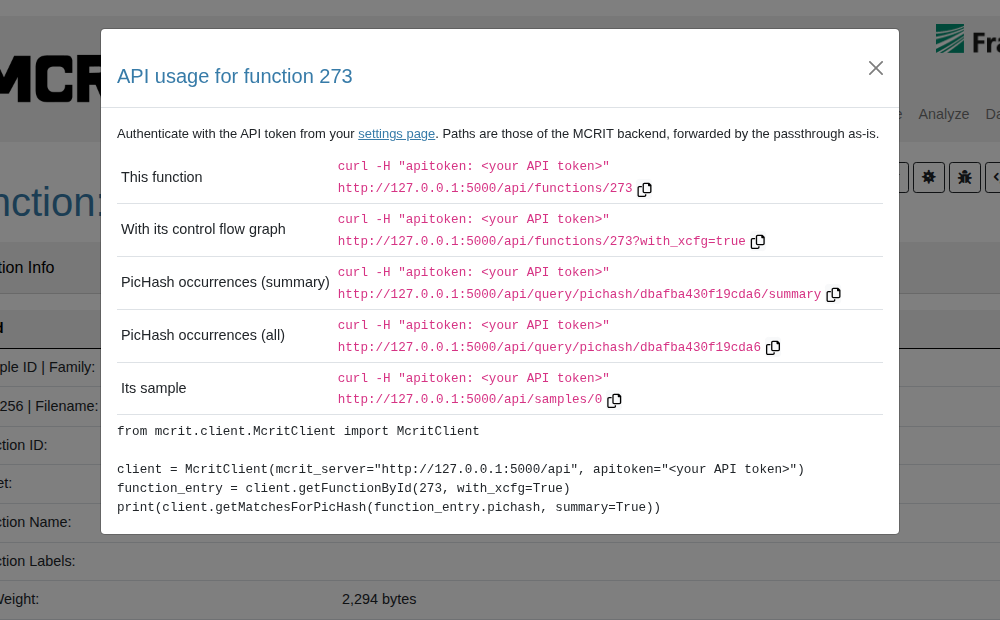
The API usage lists the requests that fetch the same data through the API passthrough, ready to paste with your own API token (see User Settings):
Statistics
Provides a short numerical summary of the MCRIT database contents.
Analyze
The Analyze section is all about matching.
There are four different methods available.
Compare 1vsN
This mode allows you to create a matching job for a sample existing in the database, which will then be compared to all other samples.
Naturally, only one input sample can be selected and the search syntax described in the Explore section applies again:

For further options, you can
- choose if you want to force a new run with
Force Rematch (e.g. in case families/samples were added/removed) or if you want to access a previous result, if existing.
- adjust the fuzziness for MinHash matching.
- Off: Only do PicHash matching, i.e. quasi-exact function matches.
- Fast: requires 3 matching bads, tightens the results but drops many matches in the lower range.
- Standard: requires 2 matching bands, which considerably filters the function candidates while not cutting off too many potential true positives.
- Complete: requires just 1 matching band, which yields the maximum number of function candidates but also likely incurs many false positives.
Compare 1vs1
In case you only want to compare two samples with each other, this is the option to choose.
This usually delivers immediate results as the matching candidate are limited to only functions found in these samples.
Cross-Compare
When wanting to compare a group of samples among each others, use Cross-Compare.
Technically, this will trigger 1vsN matching jobs for all selected samples but will also generate a comparison matrix for all samples.
This matrix is automatically ordered using hierarchical clustering and its individual fields can be clicked to get to the respective 1vs1 comparison.
The view looks like this:

The coloring scheme indicating the matching score is as follows.
Lowest score is white (no matches) or grey, then moving to red, over yellow, to green, and ending up in blue tones for the best matching scores.
Notice the strongest matches around the diagonal.
Query
When you want to match a sample against the database without adding it to the collection, you can use the Query instead.
This allows you to upload a single sample, have it disassembled, and performed a 1vsN matching job against the full database.

If the sample turns out to be interesting after all, the result page of a query offers to promote it to a full sample, so you can give it a family and a version without uploading the file a second time.
Promotion works from the copy of the upload that MCRITweb keeps under instance/temp/uploads/, because MCRIT itself does not hand a query's input back out again.
That copy only exists on the machine that received the upload through the web interface, so a query submitted through the API or the IDA plugin, or one made against a different host of the same deployment, cannot be promoted - the result page says so instead of offering the form.
Promoting a sample that is already in the collection simply takes you to it.
Unique Blocks
Unique Block Isolation generates a code-based YARA rule for a family or a chosen set of samples.
It is essentially the approach of YARA-Signator, applied to basic blocks instead of instruction n-grams: find the code that occurs inside the target set and in no other family, then build a rule from it.
There are two ways in.
The cubes button on a family row or a sample row queues the job immediately for that one family or sample and takes you to its job page.
Analyze → Unique Blocks opens a selection page instead, where you search the corpus and build up a set of samples before submitting: the backend has always accepted a list, and this is the way to give it one.
The selection is held in the URL, so it survives a reload and can be shared or bookmarked, and it is capped at 250 samples.
A sample the backend will not confirm stays in the selection and is shown as unresolved rather than being dropped — a failure to look it up is not evidence that it is gone, and silently editing the set would mean the next submit analysed something other than what you chose.
The job works in two steps.
First, elimination: MCRIT takes every basic block in the selected samples and discards any block that also occurs in a sample outside the selection.
What survives occurs in the target set and nowhere else in your collection.
Because that is a statement about your collection as it stood when the job ran, importing more samples later can make blocks that were unique no longer so, thus a rule is worth regenerating after the corpus grows.
Second, selection.
Not every unique block makes a good signature, so each surviving block is scored on two things: how many of the target samples contain it, which counts for most of the score, and how close it is to a useful signature length.
Blocks of roughly seven to ten instructions score best; shorter ones are penalised, which is what keeps short and generic blocks out of the rule, and very long ones fall away, too.
The result view has three tabs, with a summary of the job above them.

Statistics summarises how many samples went in, how many unique blocks were found across all of them, whether a YARA rule could be built at all, and how many of the input samples that rule covers.
A rule is a complete cover when every input sample contains at least one of the blocks the rule selected.
The table below breaks the same numbers down per sample, which is where you see whether one outlier is dragging the cover down.
Unique Blocks lists the surviving blocks themselves, each with its score, picblockhash, the number of input samples it appears in, its length in instructions, the function it came from, and its disassembly alongside the byte sequence a rule would use.
Three filters narrow the list — a minimum score, and a minimum and maximum block length — which together are the lever for trading coverage against confidence.
YARA Rule holds the generated rule, ready to copy — when there is one.
Blocks are chosen greedily from the scored candidates: MCRIT repeatedly takes the block covering the most samples not yet covered, until either every sample is covered or no remaining block adds anything.
That keeps the rule as short as it can be while still reaching every sample.
The rule is named mcrit_ plus a short hash of the blocks it selected, so the same selection always produces the same rule name.
Each string is the block's byte sequence with position-dependent operands wildcarded (i.e. the same normalisation PicHash uses) with the corresponding disassembly kept above it as a comment.
The condition requires 7 of the strings to match by default, or fewer if the rule has fewer strings.
That default, and the block lengths the rule is built from, can be changed on this tab.
The bounds — a minimum and maximum length in instructions, and the same in bytes — narrow the candidates before the greedy selection runs, so they change which blocks the rule is made of rather than merely hiding rows.
Tightening them trades coverage for confidence: a longer minimum gives strings that are less likely to appear by chance, and a smaller set of samples covered.
These are applied to the cached result when the page is rendered, so changing them costs nothing and does not re-run the job — which is also why they are here and not on the submit page.
A bound tight enough to exclude every block leaves a rule with no strings.
The page says so rather than offering an empty rule to copy.
Result View
All matching jobs have a Result View that allows to inspect the matching results.
When not filtered, it is usually divided into these sections:
Some meta data describing the matching job and reference sample
Once a job has finished, this table also offers "Download as JSON", which hands you the
raw result report exactly as the MCRIT server produced it - the same data the page above
is rendered from, unfiltered. This works for every job type, including from the job
overview page, and is meant for further processing outside of MCRITweb.
Best Family Matches
In the table, the best match per family is shown.

The Direct matching scores show a result that did not have ocurrence frequency weights applied.
The left number is comparable to the score that BinDiff or Diaphora would show you.
The right now shows the score minus the share of functions that have been matched to libraries.
For the frequency matching scores, each function match is additionally weighted with how many families were matched, the more families the lower the weight.
This way, less relevant matches receive less influence, and th result is boosted towards families that are more likely to have a relationship to the input sample.
Finally, the unique field gives a percentage for how many functions have been uniquely matched with this family, serving futher as an indicator or family identification.
The filter icons in each row can be used to filter the results to a specific family or sample (showing a 1vs1 result).
The filters above the table can be used to limit the initial selection.
Best Library Matches
Similar to the family view but limited to families and samples that have the library flag.
MCRIT Diagram
The MCRIT diagram visualizes the aggregated matching information for the whole sample.
Each bar corresponds to one function (with 10 or more instructions) from the binary, sorted by virtual addresses from left to right and its size being proportional to the number of instructions.
The three major rows show the following aspects:
- frequency
- library matches
- best match into another family

The coloring per row is the following.
For frequency, blue means the lowest amount of matches, going over green, yellow, red, and ending up purple.
For libraries, green indicates a match with one library and red a match with multiple libraries
For best match, dark blue indicates a PIC match (quasi-identical), and otherwise matches degrade from blue to green, to yellow, orange, and red.
Function Matches
Finally, the table at the bottom of the page shows all matches aggregated per function and the best matched function score.
Here, filtering can be used to isolate functions by score and in how many families they were matched.

When using the filter icon, only matches for the specific function_id will be shown.
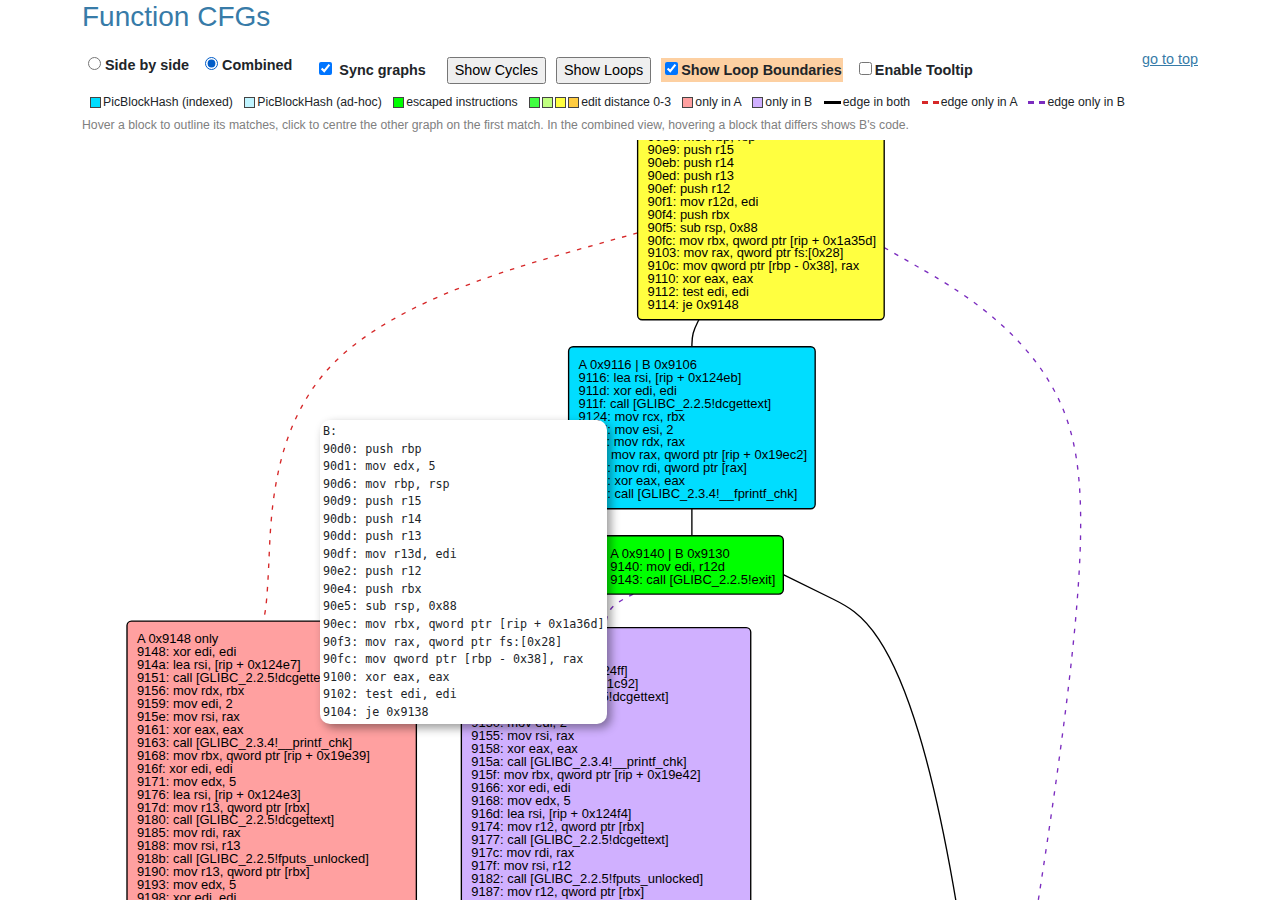
This also allows to select a match, for which a BinDiff-like function comparison can be rendered:

Here, blue indicates PIC matches (solid blue is indexed, light blue ad-hoc matched), green indicates a full match, yellow orange a partial match and red diversion that was too strong to be matched.
The two graphs are panned and zoomed together while Sync graphs is ticked, so that corresponding regions stay next to each other.
Hovering a basic block outlines the blocks it was matched to on the other side, and clicking it centers the other graph on its first match.
Combined switches to a single graph in the manner of BinDiff, in which matched blocks are drawn once with the code of function A (the code of function B is shown while hovering a block where it differs), blocks that exist only in A are red and blocks that exist only in B are purple.
Edges are black where both functions have them, and dashed red or purple where only A or only B has them.
LinkHunt
Every 1vsN result view has a Go to linkhunt report link, which asks a narrower question than the result view itself: not "what does this sample resemble", but "which of these matches suggest a relationship with another family".
The signal LinkHunt looks for first is structural.
It takes the interprocedural control flow graph of the matched sample and asks whether several functions that call or jump to one another all match the same other family.
Several connected functions matching one family together is much harder to explain away than the same number of scattered matches, so where that happens the report highlights it as a Link Cluster.
Clusters are listed with the score of the cluster as a whole, the strongest single match in it, the other family, how many functions the cluster spans, and how many of those matches are unique to that family.
Matches shown in bold are the unique ones.
This is the part of the report to read first.

Where no cluster stands out, fall back to Individual Links below, which ranks the function matches one by one.
Three things drive that ranking:
- The match score as produced by minhash, which carries the most weight of the three.
- The size of the function, with larger functions preferred and the benefit levelling off around 300 bytes.
- Its position in the binary, with functions towards the front preferred.
That compound score is then divided by a penalty that grows with the number of different families the function matched, so code that turns up across many families is pushed down.
The unpenalized family count sets how many families a function may match before that penalty starts.
Matches flagged as library are dropped from the report entirely rather than merely demoted.
The filters at the top let you tighten all of this.
They start at minimum score 65, minimum score for library matches 80, minimum link score 30, minimum function size 50 bytes, and with your own family excluded and strongest-per-family on.
Clear removes them all if you would rather start from everything and narrow by hand.
Data
The data section bundles import and export of data, including the upload of samples.
Import
The import section allows you to push previously exported data into your MCRIT instance.
The data is integrated as seamlessly as possible, sorting samples under same family names if possible.
Export
This functionality allows to export samples by ID or everything at once.
Note that the "everthing" is only suitable for smaller databases.
Jobs / Queue
Most operations in MCRIT are implemented as asynchronous jobs that are processed from a queue.
In this section, you can view all of these jobs, categorized by their type.

User / Settings
The last menu point allows you to access settings.
User Access Levels
When using a multi-user instance of MCRIT Web, this section allows management of all user accounts.
At this time, there are 4 user roles with different access rights implemented.
Pending: A user that has just registered and was not assigned a role yetVisitor: A limited "read-only" role that can not add content to the MCRIT dataase but is allowed to create matching jobs and queries with a filesize up to 1MBContributor: An account with full access rightsAdmin: A full account that can also manage other users and the server
User Settings
The user settings page allows user to edit their preferences.
On the home screen, name and registration date for the user are shown.
If the user has access level contributor or administrator, it further shows an apitoken.
This token can be used for API passthrough, using the MCRIT Web front-end as a relay when using the MCRIT python client to interact with (normally not exposed) MCRIT server.

Additionally, users with level contributor and above can also change their username and password.
All users with level visitor or above can also set a number of filter preferences, that are automatically applied to all matching results.
